Pages

Saturday, August 3, 2019

The Gaussian Mixture Model


Gaussian Mixture Model

Suppose there are a set of data points that need to be grouped into several parts or clusters based on their similarity. In machine learning, this is known as Clustering.
There are several methods available for clustering like:
In this article, the Gaussian Mixture Model will be discussed.

Normal or Gaussian Distribution

In real life, many datasets can be modeled by Gaussian Distribution (Univariate or Multivariate). So it is quite natural and intuitive to assume that the clusters come from different Gaussian Distributions. Or in other words, it is tried to model the dataset as a mixture of several Gaussian Distributions. This is the core idea of this model.
In one dimension the probability density function of a Gaussian Distribution is given by
 G(X\h|\mu, \sigma) = \frac{1}{{\sigma \sqrt {2\pi } }}e^{{{ - \left( {x - \mu } \right)^2 } \mathord{\left/ {\vphantom {{ - \left( {x - \mu } \right)^2 } {2\sigma ^2 }}} \right. \kern-\nulldelimiterspace} {2\sigma ^2 }}}
where $\mu$ and $\sigma^2$ are respectively mean and variance of the distribution.
For Multivariate ( let us say d-variate) Gaussian Distribution, the probability density function is given by
   G(X|\mu, \Sigma)= \frac{1}{\sqrt{(2\pi)|\boldsymbol\Sigma|}} \exp\left(-\frac{1}{2}({X}-{\mu})^T{\boldsymbol\Sigma}^{-1}({X}-{\mu}) \right)
Here $\mu$ is a d dimensional vector denoting the mean of the distribution and $\Sigma$ is the d X d covariance matrix.

Gaussian Mixture Model

Suppose there are K clusters (For the sake of simplicity here it is assumed that the number of clusters is known and it is K). So \mu and \Sigma is also estimated for each k. Had it been only one distribution, they would have been estimated by maximum-likelihood method. But since there are K such clusters and the probability density is defined as a linear function of densities of all these K distributions, i.e.
p(X) =\sum_{k=1}^K \pi_k G(X|\mu_k, \Sigma_k)
where \pi_k is the mixing coefficient for k-th distribution.
For estimating the parameters by maximum log-likelihood method, compute p(X|\mu, \Sigma, \pi).
 ln\hspace{0.25 cm} {p( X|\mu, \Sigma, \pi)} \newline =\sum_{i=1}^N p(X_i) \newline =\sum_{i=1}^N ln {\sum_{k=1}^K \pi_k G(X_i | \mu_k, \Sigma_k)}
Now define a random variable \gamma_k(X) such that \gamma_k(X)=p(k|X).
From Bayes’theorem,
 \gamma_k(X) \newline\newline=\frac{p(X|k)p(k)}{\sum_{k=1}^K p(k)p(X|k)} \newline\newline=\frac{p(X|k)\pi_k}{\sum_{k=1}^K \pi_k p(X|k)}
Now for the log likelihood function to be maximum, its derivative of p(X|\mu, \Sigma, \pi)with respect to  \mu, \Sigma and \pi should be zero. So equaling the derivative of p(X|\mu, \Sigma, \pi) with respect to \mu to zero and rearranging the terms,
\mu_k=\frac{\sum_{n=1}^N \gamma_k(x_n)x_n}{\sum_{n=1}^N \gamma_k(x_n)}
Similarly taking derivative with respect to \Sigma and \pi respectively, one can obtain the following expressions.
 \Sigma_k=\frac{\sum_{n=1}^N \gamma_k(x_n)(x_n-\mu_k)(x_n-\mu_k)^T}{\sum{n=1}^N \gamma_k(x_n)} \newline
And
  \pi_k=\frac{1}{N} \sum_{n=1}^N \gamma_k(x_n)
Note: \sum_{n=1}^N\gamma_k(x_n) denotes the total number of sample points in the k-th cluster. Here it is assumed that there are total N number of samples and each sample containing d features are denoted by x_i.
So it can be clearly seen that the parameters cannot be estimated in closed form. This is where Expectation-Maximization algorithm is beneficial.

Expectation-Maximization (EM) Algorithm

The Expectation-Maximization (EM) algorithm is an iterative way to find maximum-likelihood estimates for model parameters when the data is incomplete or has some missing data points or has some hidden variables. EM chooses some random values for the missing data points and estimates a new set of data. These new values are then recursively used to estimate a better first data, by filling up missing points, until the values get fixed.
These are the two basic steps of the EM algorithm, namely E Step or Expectation Step or Estimation Step and M Step or Maximization Step.
  • Estimation step:
    • initialize \mu_k, \Sigma_k and \pi_k by some random values, or by K means clustering results or by hierarchical clustering results.
    • Then for those given parameter values, estimate the value of the latent variables (i.e \gamma_k)
  • Maximization Step:
    • Update the value of the parameters( i.e. \mu_k, \Sigma_k and\pi_k) calculated using ML method.
Algorithm:
  1. Initialize the mean \mu_k, the covariance matrix \Sigma_k and the mixing coefficients \pi_k by some random values. (or other values)
  2. Compute the \gamma_k values for all k.
  3. Again Estimate all the parameters using the current \gamma_k values.
  4. Compute log-likelihood function.
  5. Put some convergence criterion
  6. If the log-likelihood value converges to some value ( or if all the parameters converge to some values ) then stop, else return to Step 2.
Example:
In this example, IRIS Dataset is taken. In Python there is a GaussianMixture class to implement GMM.
Note: This code might not run in an online compiler. Please use an offline ide.
  1. Load the iris dataset from datasets package. To keep things simple, take only first two columns (i.e sepal length and sepal width respectively).
  2. Now plot the dataset.
    filter_none
    brightness_4
    import numpy as np
    import pandas as pd
    import matplotlib.pyplot as plt
    from pandas import DataFrame
    from sklearn import datasets
    from sklearn.mixture import GaussianMixture
      
    # load the iris dataset
    iris = datasets.load_iris()
      
    # select first two columns 
    X = iris.data[:, :2]
      
    # turn it into a dataframe
    d = pd.DataFrame(X)
      
    # plot the data
    plt.scatter(d[0], d[1])
  3. Now fit the data as a mixture of 3 Gaussians.
  4. Then do the clustering, i.e assign a label to each observation. Also find the number of iterations needed for the log-likelihood function to converge and the converged log-likelihood value.
    filter_none
    brightness_4
    gmm = GaussianMixture(n_components = 3)
      
    # Fit the GMM model for the dataset 
    # which expresses the dataset as a 
    # mixture of 3 Gaussian Distribution
    gmm.fit(d)
      
    # Assign a label to each sample
    labels = gmm.predict(d)
    d['labels']= labels
    d0 = d[d['labels']== 0]
    d1 = d[d['labels']== 1]
    d2 = d[d['labels']== 2]
      
    # plot three clusters in same plot
    plt.scatter(d0[0], d0[1], c ='r')
    plt.scatter(d1[0], d1[1], c ='yellow')
    plt.scatter(d2[0], d2[1], c ='g')
  5. Print the converged log-likelihood value and no. of iterations needed for the model to converge
    filter_none
    brightness_4
    # print the converged log-likelihood value
    print(gmm.lower_bound_)
      
    # print the number of iterations needed
    # for the log-likelihood value to converge
    print(gmm.n_iter_)</div>
  6. Hence, it needed 7 iterations for the log-likelihood to converge. If more iterations are performed, no appreciable change in the log-likelihood value, can be observed.
For more discussions about GMM...you can visit the website below.


Statistical Mathematics Book Reference

Mathematical statistics is the application of probability theory, a branch of mathematics, to statistics, as opposed to techniques for collecting statistical data.
Here are some of the books related to statistical mathematics book for your referral. Just click the link below and enjoy reading. Thank you!
Hope this could help for those looking for a book for statistical mathematical concepts. 

1. http://www.math.louisville.edu/Math662TB-09S.pdf

2. https://stat.ethz.ch/~geer/mathstat.pdf

3. http://www.maths.adelaide.edu.auMSIII2012/MSIII.pdf

4. https://fac.ksu.edu.sa/sites/


Prepared by:
EOM

HOW CAN I MAKE A BAR GRAPH WITH ERROR BARS?

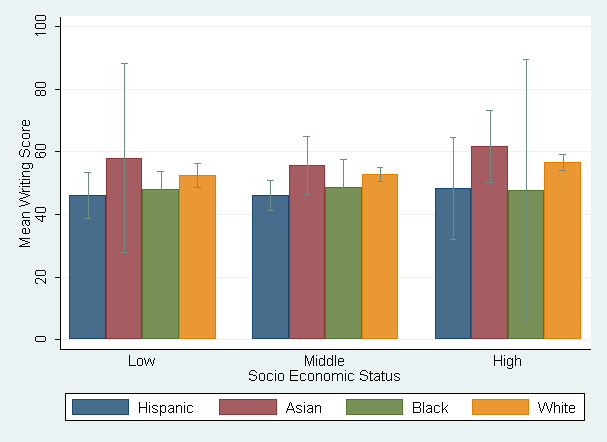
Say that you were looking at writing scores broken down by race and ses.  You might want to graph the mean and confidence interval for each group using a bar chart with error bars as illustrated below. This FAQ shows how you can make a graph like this, building it up step by step.
Image barcap1
First, lets get the data file we will be using.
use https://stats.idre.ucla.edu/stat/stata/notes/hsb2, clear
Now, let’s use the collapse command to make the mean and standard deviation by race and ses.
collapse (mean) meanwrite= write (sd) sdwrite=write (count) n=write, by(race ses)
Now, let’s make the upper and lower values of the confidence interval.
generate hiwrite = meanwrite + invttail(n-1,0.025)*(sdwrite / sqrt(n))
generate lowrite = meanwrite - invttail(n-1,0.025)*(sdwrite / sqrt(n))
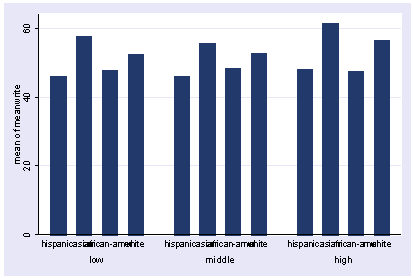
Now we are ready to make a bar graph of the data The graph bar command makes a pretty good bar graph.
graph bar meanwrite, over(race) over(ses)
Image barcap2
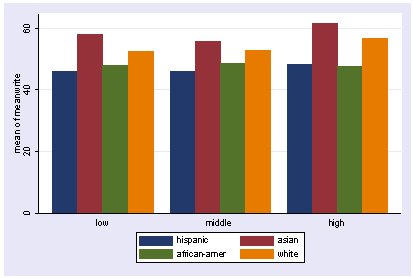
We can make the graph look a bit prettier by adding the asyvars option as shown below.
graph bar meanwrite, over(race) over(ses) asyvars 
Image barcap3
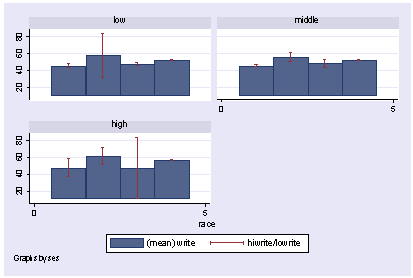
But, this graph does not have the error bars in it. Unfortunately, as nice as the graph bar command is, it does not permit error bars. However, we can make a twoway graph that has error bars as shown below. Unfortunately, this graph is not as attractive as the graph from graph bar.
graph twoway (bar meanwrite race) (rcap hiwrite lowrite race), by(ses)
Image barcap4
So, we have a conundrum. The graph bar command will make a lovely bar graph, but will not support error bars. The twoway bar command makes lovely error bars, but it does not resemble the nice graph that we liked from the graph bar command. However, we can finesse the twoway bar command to make a graph that resembles the graph bar command and then combine that with error bars. Here is a step by step process.
First, we will make a variable sesrace that will be a single variable that contains the ses and race information. Note how sesrace has a gap between the levels of ses (at 5 and 10).
generate sesrace = race    if ses == 1
replace  sesrace = race+5  if ses == 2
replace  sesrace = race+10 if ses == 3
sort sesrace
list sesrace ses race, sepby(ses)

     +---------------------------------+
     | sesrace      ses           race |
     |---------------------------------|
  1. |       1      low       hispanic |
  2. |       2      low          asian |
  3. |       3      low   african-amer |
  4. |       4      low          white |
     |---------------------------------|
  5. |       6   middle       hispanic |
  6. |       7   middle          asian |
  7. |       8   middle   african-amer |
  8. |       9   middle          white |
     |---------------------------------|
  9. |      11     high       hispanic |
 10. |      12     high          asian |
 11. |      13     high   african-amer |
 12. |      14     high          white |
     +---------------------------------+
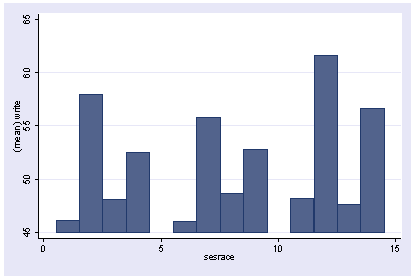
Now, we will make a graph using graph twoway. Notice how the bars are in three groups of four bars. The three groups correspond to the three levels of ses and the four bars within each group correspond to the four levels of race. You can relate this grouping to the way that we constructed raceses above.
twoway (bar meanwrite sesrace)
Image barcap5
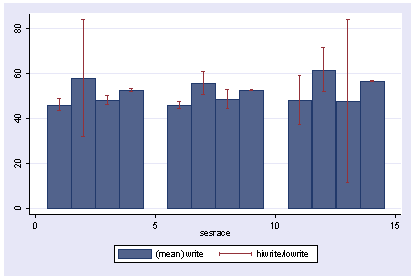
We can now overlay the error bars by overlaying a rcap graph
twoway (bar meanwrite sesrace) (rcap hiwrite lowrite sesrace)
Image barcap6
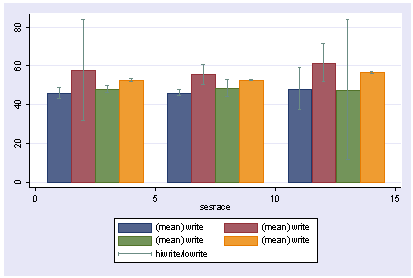
This kind of looks like what we want, but it would look nicer if each of the bars for the four different races were different colors. We can do this by overlaying four separate bar graphs, one for each racial group.
twoway (bar meanwrite sesrace if race==1) ///
       (bar meanwrite sesrace if race==2) ///
       (bar meanwrite sesrace if race==3) ///
       (bar meanwrite sesrace if race==4) ///
       (rcap hiwrite lowrite sesrace)
Image barcap7
This is looking better, but let’s use the legend to label the bars better.
twoway (bar meanwrite sesrace if race==1) ///
       (bar meanwrite sesrace if race==2) ///
       (bar meanwrite sesrace if race==3) ///
       (bar meanwrite sesrace if race==4) ///
       (rcap hiwrite lowrite sesrace), ///
       legend( order(1 "Hispanic" 2 "Asian" 3 "Black" 4 "White") )
Image barcap8
The legend labels the bars nicely but would look cleaner if it were just one row and the x axis of the graph does not convey that the three groups of bars correspond to the three groups of ses. We can use the xlabel() option to remedy that. We also add better titles for the x and y axes as well.
twoway (bar meanwrite sesrace if race==1) ///
       (bar meanwrite sesrace if race==2) ///
       (bar meanwrite sesrace if race==3) ///
       (bar meanwrite sesrace if race==4) ///
       (rcap hiwrite lowrite sesrace), ///
       legend(row(1) order(1 "Hispanic" 2 "Asian" 3 "Black" 4 "White") ) ///
       xlabel( 2.5 "Low" 7.5 "Middle" 12.5 "High", noticks) ///
       xtitle("Socio Economic Status") ytitle("Mean Writing Score")
Image barcap9
Now we have a graph that looks like the kind of graph that we would get from graph bar but by finessing graph twoway bar into making this pretty graph, we could then overlay the rbar graph to get the error bars we desired.
Prepared by:
Neil M.

Source: 

Statistical Methods for Social Sciences by Ofosu & Hesse

STATISTICAL METHODS IN SOCIAL SCIENCES


Statistical methods are mathematical formulas, models, and techniques that are used in the statistical analysis of raw research data. The application of statistical methods extracts information from research data and provides different ways to assess the robustness of research outputs.


You are looking for a book related to statistics for social sciences here is a suggestion for you.


Click the link below:

https://www.academia.edu/35827812/


Friday, August 2, 2019

Types of Regression Analysis

Types of Regression

What are the types of Regressions? Here they are:

Linear Regression

Logistic Regression

Polynomial Regression

Stepwise Regression

Ridge Regression

Lasso Regression

ElasticNet Regression

1. Linear Regression

It is one of the most widely known modeling technique. Linear regression is usually among the first few topics which people pick while learning predictive modeling. In this technique, the dependent variable is continuous, the independent variable(s) can be continuous or discrete, and the nature of the regression line is linear.

Linear Regression establishes a relationship between the dependent variable (Y) and one or more independent variables (X) using a best fit straight line (also known as a regression line).

It is represented by an equation Y=a+b*X + e, where a is intercept, b is the slope of the line and e is error term. This equation can be used to predict the value of the target variable based on a given predictor variable(s).

2. Logistic Regression

Logistic regression is used to find the probability of event=Success and event=Failure. We should use logistic regression when the dependent variable is binary (0/ 1, True/ False, Yes/ No) in nature. Here the value of Y ranges from 0 to 1 and it can be represented by the following equation.

odds= p/ (1-p) = probability of event occurrence / probability of not event occurrence
ln(odds) = ln(p/(1-p))
logit(p) = ln(p/(1-p)) = b0+b1X1+b2X2+b3X3....+bkXk

Above, p is the probability of the presence of the characteristic of interest. A question that you should ask here is “why have we used to log in the equation?”.

Since we are working here with a binomial distribution (dependent variable), we need to choose a link function which is best suited for this distribution. And, it is a logit function. In the equation above, the parameters are chosen to maximize the likelihood of observing the sample values rather than minimizing the sum of squared errors (like in ordinary regression).

3. Polynomial Regression

A regression equation is a polynomial regression equation if the power of the independent variable is more than 1. The equation below represents a polynomial equation:

y=a+b*x^2

In this regression technique, the best fit line is not a straight line. It is rather a curve that fits into the data points.

4. Stepwise Regression

This form of regression is used when we deal with multiple independent variables. In this technique, the selection of independent variables is done with the help of an automatic process, which involves no human intervention.

This feat is achieved by observing statistical values like R-square, t-stats and AIC metric to discern significant variables. Stepwise regression basically fits the regression model by adding/dropping co-variates one at a time based on a specified criterion. Some of the most commonly used Stepwise regression methods are listed below:
Standard stepwise regression does two things. It adds and removes predictors as needed for each step.

Forward selection starts with the most significant predictor in the model and adds variable for each step.

Backward elimination starts with all predictors in the model and removes the least significant variable for each step.

The aim of this modeling technique is to maximize the prediction power with a minimum number of predictor variables. It is one of the methods to handle higher dimensionality of data set.

5. Ridge Regression

Ridge Regression is a technique used when the data suffers from multicollinearity ( independent variables are highly correlated). In multicollinearity, even though the least squares estimates (OLS) are unbiased, their variances are large which deviates the observed value far from the true value. By adding a degree of bias to the regression estimates, ridge regression reduces the standard errors.

Above, we saw the equation for linear regression. Remember? It can be represented as:

y=a+ b*x

This equation also has an error term. The complete equation becomes:

y=a+b*x+e (error term), [error term is the value needed to correct for a prediction error between the observed and predicted value]

=> y=a+y= a+ b1x1+ b2x2+....+e, for multiple independent variables.

In a linear equation, prediction errors can be decomposed into two sub-components. First is due to the biased and second is due to the variance. Prediction error can occur due to any one of these two or both components. Here, we’ll discuss the error caused due to variance.

6. Lasso Regression

lasso regression, l1 regularization

Similar to Ridge Regression, Lasso (Least Absolute Shrinkage and Selection Operator) also penalizes the absolute size of the regression coefficients. In addition, it is capable of reducing the variability and improving the accuracy of linear regression models. Look at the equation below: Lasso regression differs from ridge regression in a way that it uses absolute values in the penalty function, instead of squares. This leads to penalizing (or equivalently constraining the sum of the absolute values of the estimates) values which causes some of the parameter estimates to turn out exactly zero. Larger the penalty applied, further the estimates get shrunk towards absolute zero. This results in variable selection out of given n variables.

7. ElasticNet Regression

ElasticNet is a hybrid of Lasso and Ridge Regression techniques. It is trained with L1 and L2 prior as regularizer. Elastic-net is useful when there are multiple features which are correlated. Lasso is likely to pick one of these at random, while elastic-net is likely to pick both.

elastic net regression

A practical advantage of trading-off between Lasso and Ridge is that it allows Elastic-Net to inherit some of Ridge’s stability under rotation.

How to select the right regression model?

Life is usually simple when you know only one or two techniques. One of the training institutes I know of tells their students – if the outcome is continuous – apply linear regression. If it is binary – use logistic regression! However, higher the number of options available at our disposal, more difficult it becomes to choose the right one. A similar case happens with regression models.

Within multiple types of regression models, it is important to choose the best-suited technique based on the type of independent and dependent variables, dimensionality in the data and other essential characteristics of the data. Below are the key factors that you should practice to select the right regression model:
Data exploration is an inevitable part of building a predictive model. It should be your first step before selecting the right model like identify the relationship and impact of variables

To compare the goodness of fit for different models, we can analyze different metrics like the statistical significance of parameters, R-square, Adjusted r-square, AIC, BIC and error term. Another one is Mallow’s Cp criterion. This essentially checks for possible bias in your model, by comparing the model with all possible submodels (or a careful selection of them).

Cross-validation is the best way to evaluate models used for prediction. Here you divide your data set into two groups (train and validate). A simple mean squared difference between the observed and predicted values give you a measure for the prediction accuracy.

If your data set has multiple confounding variables, you should not choose the automatic model selection method because you do not want to put these in a model at the same time.

It’ll also depend on your objective. It can occur that a less powerful model is easy to implement as compared to a highly statistically significant model.

Regression regularization methods(Lasso, Ridge, and ElasticNet) works well in case of high dimensionality and multicollinearity among the variables in the data set.

By now, I hope you would have got an overview of regression. These regression techniques should be applied considering the conditions of data. One of the best tricks to finding out which technique to use is by checking the family of variables i.e. discrete or continuous.

End note...